You run Ollama. Haybox decides when it’s enough.
If Ollama is already serving models on your machine, Haybox treats it as the local tier and escalates past it only on evidence.
Three steps
Point Ollama at the Haybox daemon and keep working. The exact configuration line for your version is in the docs.
- Install Haybox
One binary, Windows, macOS or Linux. It starts a local daemon and detects your hardware.
- Point Ollama at the local endpoint
Leave Ollama running. Haybox discovers it and the models you already have.
- Work normally
Nothing about your workflow changes. Watch the Ledger fill: a Waybill per task, and a savings report after thirty days.
Haybox is in private alpha, so step one is the waitlist for now.
What you get with Ollama
- A shadow report built from your real traffic, not a simulation of someone else’s.
- Local-first routing with acceptance floors under it, so cheap only counts when it holds.
- A Waybill per task: the route, the cost per leg, what verified, and your decision.
- Rules that apply here too — the files you already keep are read natively.
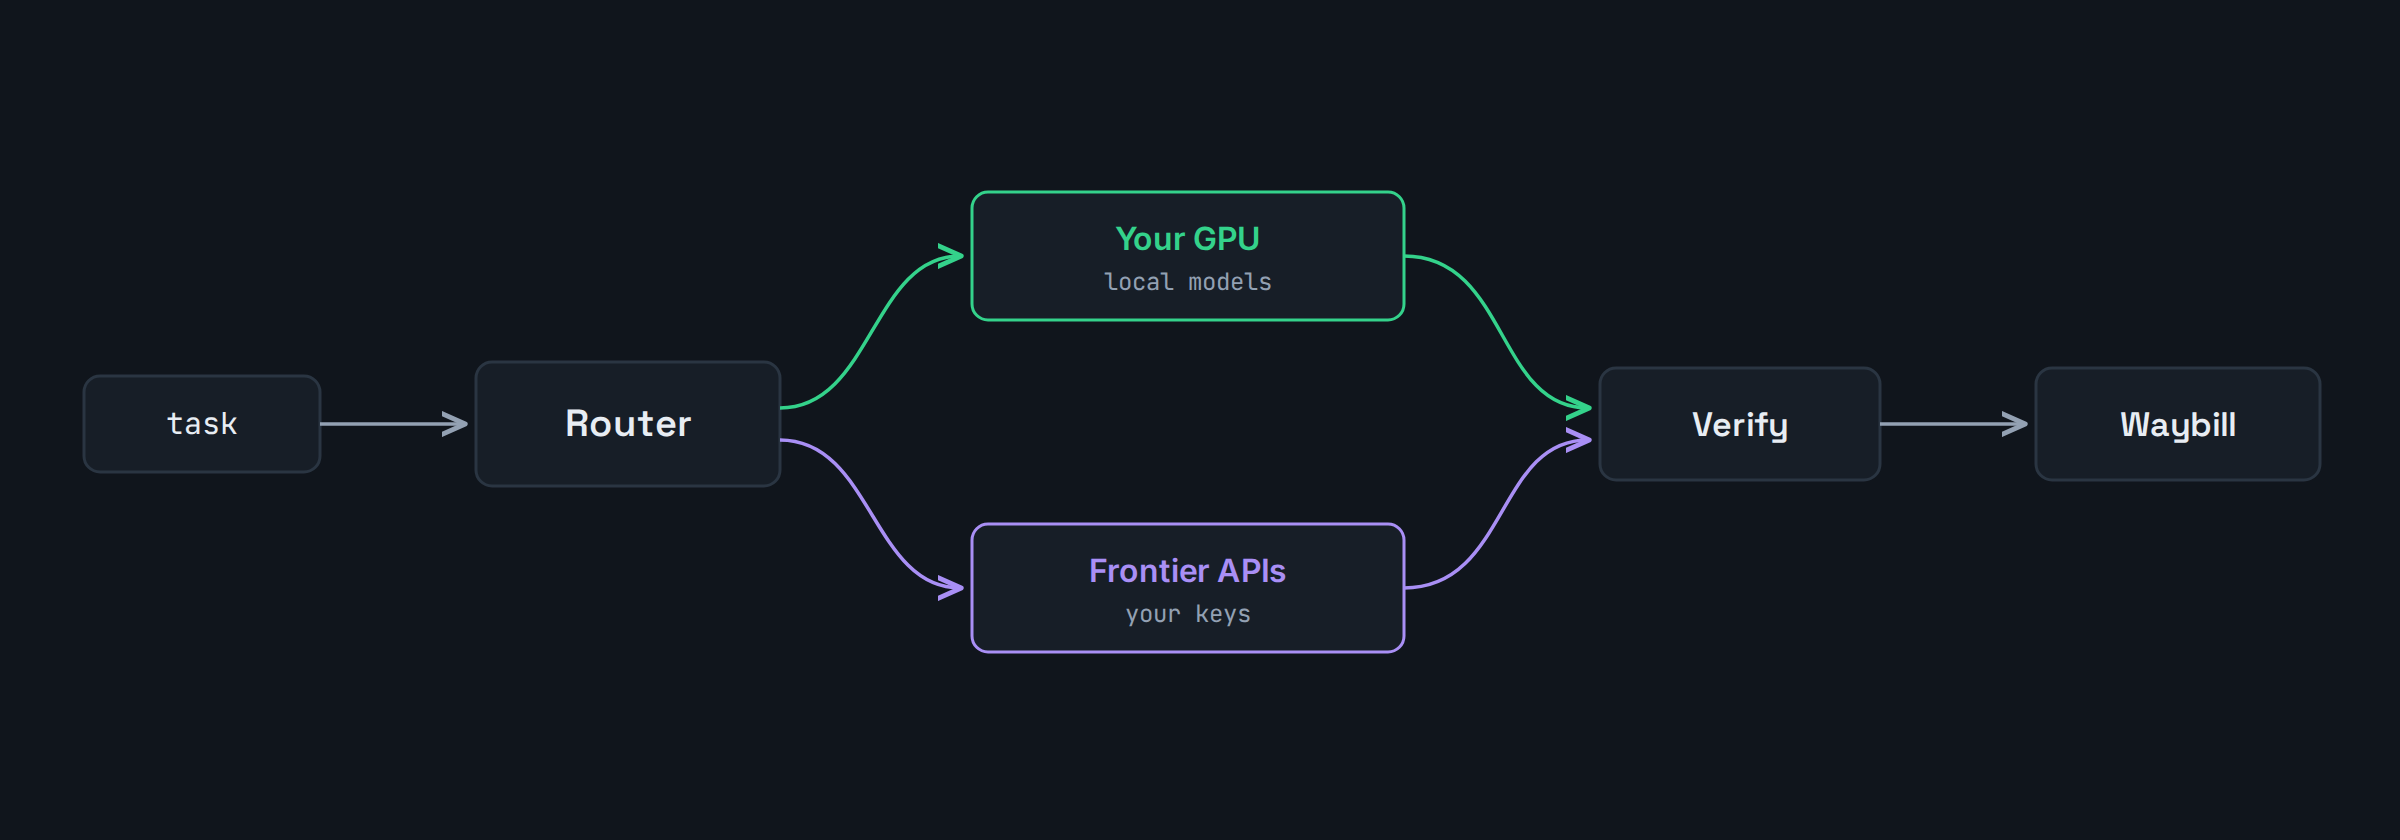
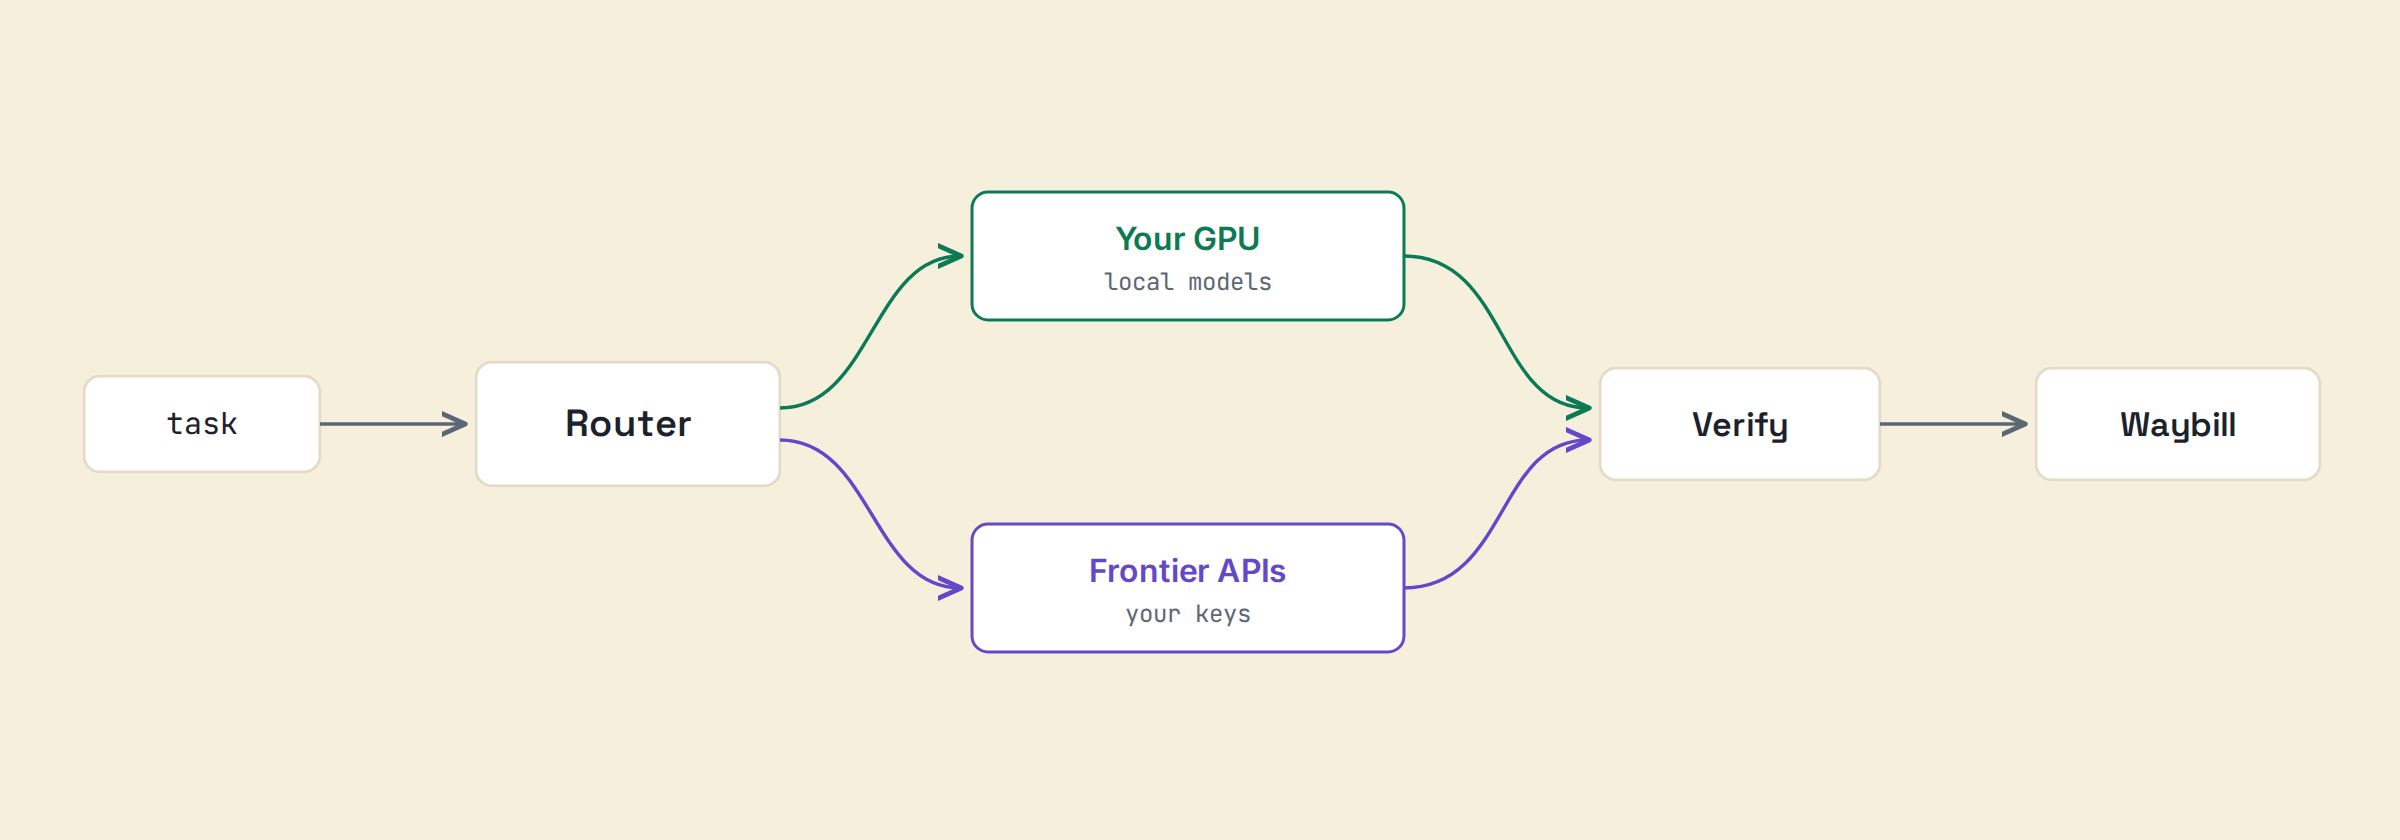
The route, end to end. Illustrative.
Notes for Ollama specifically
If Ollama is already serving models on your machine, Haybox treats it as the local tier: it discovers what you have, uses it for the work it holds quality on, and escalates past it on evidence. The Model Manager can also drive new installs through Ollama, so recommendations become one click instead of a pull command you had to research.
Questions
Does Haybox replace Ollama?
No; it routes to it.
What about my existing models?
Discovered and used; recommendations are additive.
LM Studio · Claude Code · Local Model Manager · All integrations
See what your own traffic says.
Shadow Mode reports on the traffic you already have. Before that exists for you, the calculator will estimate it from your GPU and your monthly spend, and show you every assumption it used to get there.